If you’ve ever wondered what billions of AI requests actually look like under the hood, now you can find out. Chutes, a decentralized AI inference platform running on Bittensor’s Subnet 64, has teamed up with Harvard University researchers to release what may be the largest public dataset of LLM serving metadata ever assembled. The numbers are staggering: 6,122,413,756 requests across 9,174 models, generated by 314,970 anonymized users over a full year of production traffic. The dataset spans from April 11, 2025, to April 12, 2026, and is now freely available through GitHub and a Harvard S3 bucket. What’s actually in this thing The dataset captures metadata, not the actual conversations people had with AI models. It includes request timing, token counts, latency measurements, and time-to-first-token (TTFT) metrics, but zero prompts or responses. Over the year-long period, Chutes processed roughly 35.8 trillion input tokens and 2.52 trillion output tokens. User identifiers in the dataset rotate every three months, adding another layer of anonymization. The accompanying documentation, co-authored by researchers from Harvard, the University of Chicago, and Chutes, provides the kind of...
Chutes AI and Harvard release public dataset of 6.12 billion LLM requests
 1 hour ago
2
Related

AI Predicts Solana’s Next Move as Short Sellers Get Squeezed...
6 minutes ago
0
Bittensor projects generate $28M-$35M in annualized revenue,...
23 minutes ago
0
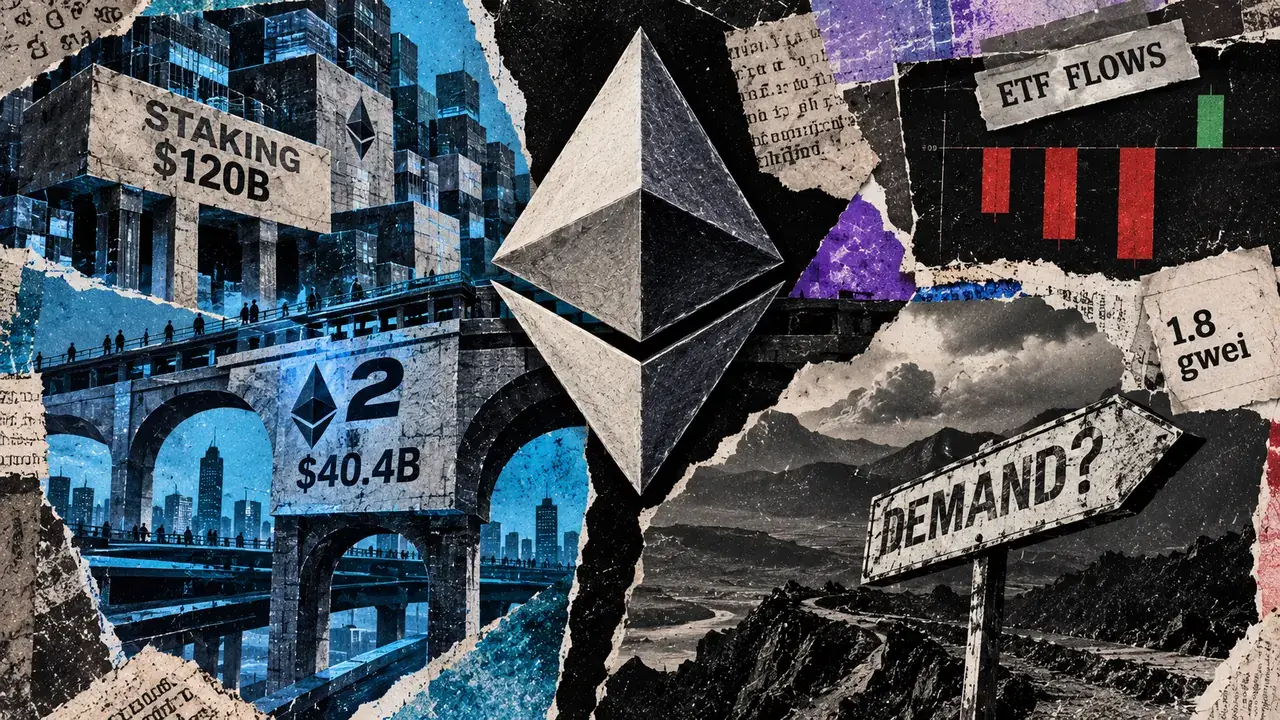
L2 growth and $120 billion in staking hide Ethereum’s supply...
23 minutes ago
1

Strategy Buys Another 950 Bitcoin As Holdings Reach 846,000 ...
34 minutes ago
0
TypeSafe opens Jev AI to public after rapid adoption forces ...
36 minutes ago
0
Brian Armstrong: CLARITY Act Failure Could Benefit Coinbase
47 minutes ago
0
X enables crypto trading directly on user timelines with par...
55 minutes ago
0

Popular


Starknet shields 45 assets with new privacy framework
1 week ago
54



 English (US) ·
© Clint's Cryto News 2026. All rights are reserved
