When you ask an AI to judge a writing contest and one of the contestants is itself, things get awkward. New research examining self-preference bias in large language models finds that AI judges favor their own generated responses roughly 58% of the time in pairwise comparisons. The findings cut to the heart of a growing dependency in the AI industry: using models to evaluate other models. Platforms like Chatbot Arena, which pit AI systems against each other in blind head-to-head matchups, have become de facto benchmarks for measuring progress. The narcissism problem The bias, sometimes called egocentric or narcissistic bias, shows up consistently across the industry’s biggest names. OpenAI’s GPT, Anthropic’s Claude, and Google’s Gemini all exhibit the tendency when placed in judging roles. Research suggests that somewhere between 40% and 96% of the observed self-preference could stem from actual quality differences in the outputs being compared. In other words, some models might genuinely prefer their own answers because those answers are, by certain metrics, better. One way researchers have tried to tease this apart is through perplexity, a measure of how surprised a model is by a...
Arena study shows AI models prefer their own answers 58% of the time
 1 week ago
17
Related
First National Bank opens Bitcoin trading to nearly 9 millio...
19 minutes ago
0
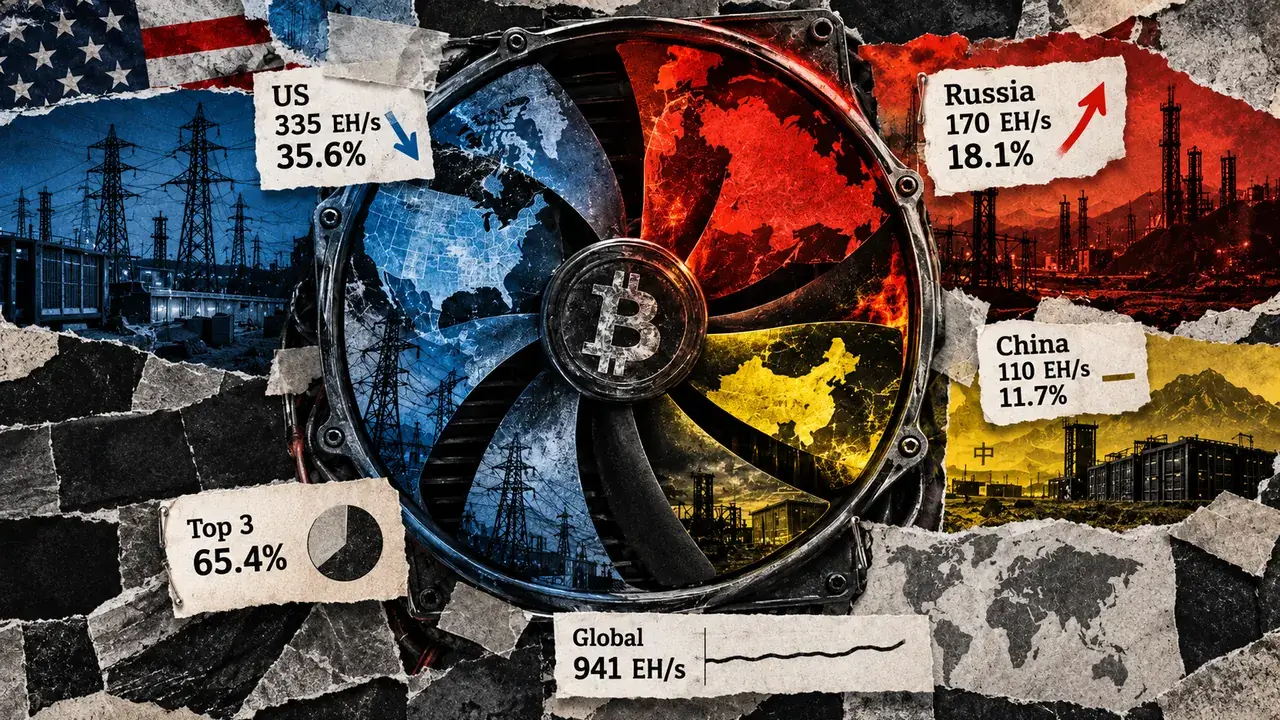
3 countries control 66% of Bitcoin mining, but 1 rival is ga...
24 minutes ago
1
Securitize, LG CNS partner on tokenized assets in South Kore...
29 minutes ago
0
Altcoins Are Rallying, But Analyst Says Alt Season Has Yet t...
33 minutes ago
0
UK names 6 banks to lead first digitally native government b...
36 minutes ago
0

Anthropic expands Cyber Verification Program with new access...
48 minutes ago
0
Winklevoss files for spot Zcash ETF as ZEC price climbs abov...
49 minutes ago
0
Saudi-backed forces launch campaign against Houthis after Re...
58 minutes ago
1
Popular

Starknet shields 45 assets with new privacy framework
4 weeks ago
100


Chainflip loses 736,442 USDT in TRON exploit
3 weeks ago
42
 English (US) ·
© Clint's Cryto News 2026. All rights are reserved
